AI Dance Video Generator
AI Dance Video
From Your Photo —
Real Motion, Not Presets.
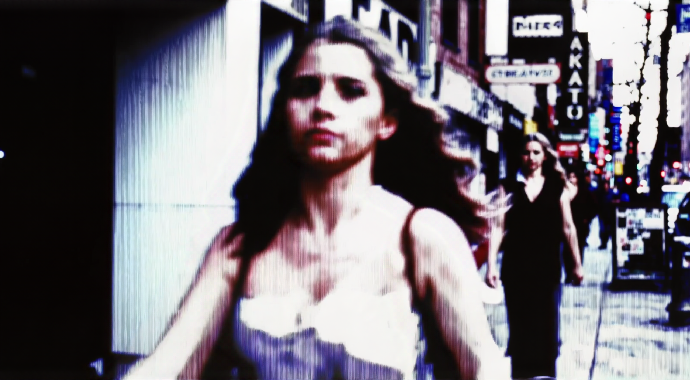
Upload a photo of the dancer and direct the move in the prompt. Reference conditioning keeps their identity through the clip while Wan 3.0's motion engine renders weight, momentum, and follow-through. No rigged preset routines, no subscription.
Model Options
Choose the workflow that fits your scene
Start with a prompt, add references when needed, and pick the generation path that matches the output.
Wan 3.0 for dance that carries weight
Dance reads or dies on physics: the compression of a landing, the swing path of an arm, hair and fabric catching the beat a frame late. Wan 3.0 renders that as filmed motion instead of floaty generative drift, and it is the engine for clips where the movement itself is the content.
Wan 3.0 R2V when the dancer is the point
Reference-to-video conditions the render on your upload: one photo of the dancer (or you) defines identity, and the model places that person in new scenes, outfits, and angles while they stay recognizably themselves. Direct the choreography in the prompt and re-use the same reference for every take.
Seedance 2.0 R2V for performance framing
When the clip should read as a performance rather than a rehearsal-room phone video: Seedance 2.0's reference mode handles stage lighting, crowd context, and deliberate camera moves with cinematic framing, so a concept pitch arrives looking produced.
Example Outputs
Dance clips made with reference conditioning
Real outputs from Wan 3.0 R2V and Seedance 2.0 R2V — your photo keeps its identity while the motion carries weight.


Why use it on Moosky AI
Why dancers and studios skip the preset apps
Preset apps run your face through a rigged avatar and three canned routines. Moosky runs the same job with reference conditioning and physics-grade video models — you direct the motion, the models do the filming.
Motion with weight and follow-through
Jumps land with compression, turns carry momentum, hair and cloth trail the beat. The physics is what separates a dance clip from a screensaver.
Your photo stays the dancer
Reference conditioning locks the face, body, and outfit from your upload, so the clip stars your dancer through every take and scene change.
You direct the choreography
Prompt the move: footwork, isolations, formations, the count it lands on. Preset apps loop canned routines; here the routine is whatever you write.
Vertical, stage, or square
Frame for the feed it ships to: 9:16 for Shorts, Reels, and TikTok, widescreen for stage footage, square for the grid.
Draft cheap, keep the winner
Try framings on LTX 2.5 at a fraction of the credits, then re-render the take that holds a watch on Wan 3.0. The credit quote shows before every run.
Credits per clip, watermark-free
Pay for the clips you publish, get refunds on failed renders, and download clean files for monetized feeds and client work.
How It Works
Three steps from a photo to a posted dance clip
Upload the dancer
One clear photo sets the identity — your face, your dancer, your client. Standing height, even light, and the outfit you want on screen work best.
Write the routine
Prompt the choreography, setting, and camera the way you would brief a videographer: the steps, the count they land on, the framing. Draft the wild ones cheap on LTX 2.5.
Render and post
Run the winning take on Wan 3.0, keep the same reference for variations, and download the vertical cut watermark-free for the feed or the pitch.
Direct the motion instead of picking a template
The preset dance apps all share one trick: your face pasted onto a rigged skeleton, running a routine somebody else choreographed, in one of three canned outfits. It works for a laugh and fails the moment you need something specific — the hook you actually choreographed, the stage look a client asked to see, the teaser a studio wants before rehearsals start.
Moosky runs the job the way short-form video gets made now. One photo of the dancer conditions the render, so identity survives every take. The choreography lives in your prompt — footwork, isolations, formations, the count it lands on. Wan 3.0 renders the physics that make movement read as real: landings compress, turns carry momentum, hair and fabric trail a beat late. LTX 2.5 drafts framings cheap so credits go to the best take.
In practice: a creator auditions three hook variations and posts the winner; a choreographer pitches a stage concept with lighting and wardrobe already in frame; a wedding studio turns one rehearsal photo into a save-the-date teaser before the videographer is booked.
Credit-based
Simple, honest pricing
No subscriptions. No hidden fees. Pay only for the credits you use.
More from Moosky AI
Explore our complete suite of AI tools.
Frequently Asked Questions
How does an AI dance video generator work?
Two parts. A reference-conditioned model (like Wan 3.0 R2V) takes one photo and locks the dancer's identity into the render, so the same person carries through the clip. The motion itself comes from the prompt — you describe the routine, the camera, and the setting, and a physics-grade model renders it as filmed movement. Unlike preset apps, nothing is a canned loop; the choreography is whatever you write.
Can I turn a photo into a dance video?
Yes — that is the main flow here. Upload a clear photo of the dancer, pick Wan 3.0 R2V, and prompt the move and setting. One photo defines identity; every take keeps that face, body, and outfit while you change scenes, outfits in the description, or camera angle. Studios run the same flow on a single rehearsal snapshot.
Can the AI keep my actual choreography?
You direct it in words rather than uploading a video to copy. Write the routine the way you would brief a videographer: the steps, their counts, the level changes, where the turn lands. Wan 3.0's physics decides how the body moves through those beats — weight on landings, momentum in turns — so your description reads as real movement instead of a looped animation.
Which AI model makes the best dance motion?
Wan 3.0, for the reason dancers notice first: it renders weight, collision, and follow-through as filmed motion, so jumps, turns, and floor work look like a body moving rather than a puppet sliding. Use Wan 3.0 R2V when the dancer's identity must match a real person, Seedance 2.0 R2V for stage and event framing, and LTX 2.5 for cheap drafts.
What does an AI dance video cost to make?
Credits per rendered clip — 100 credits per dollar, the exact quote appears in the composer before every run, and failed renders are refunded. There is no subscription, unused credits never expire, and downloads are watermark-free, so monetized uploads and client deliverables need no extra step. Drafting on LTX 2.5 costs a fraction of the premium pass.
Disclosure
Moosky AI is an independent platform provider and reseller of AI model access. Product names, model names, and company names shown on this page belong to their respective owners. Moosky AI is not officially affiliated with, sponsored by, or endorsed by those providers unless expressly stated. Page content, examples, and previews may include AI-assisted and synthetic content.